MastiDB
An on-disk OLAP database engine, built from scratch in Python.
Experiment · Open source · Started 2023, revived 2026 · Python, compiled with MyPyC
What it is
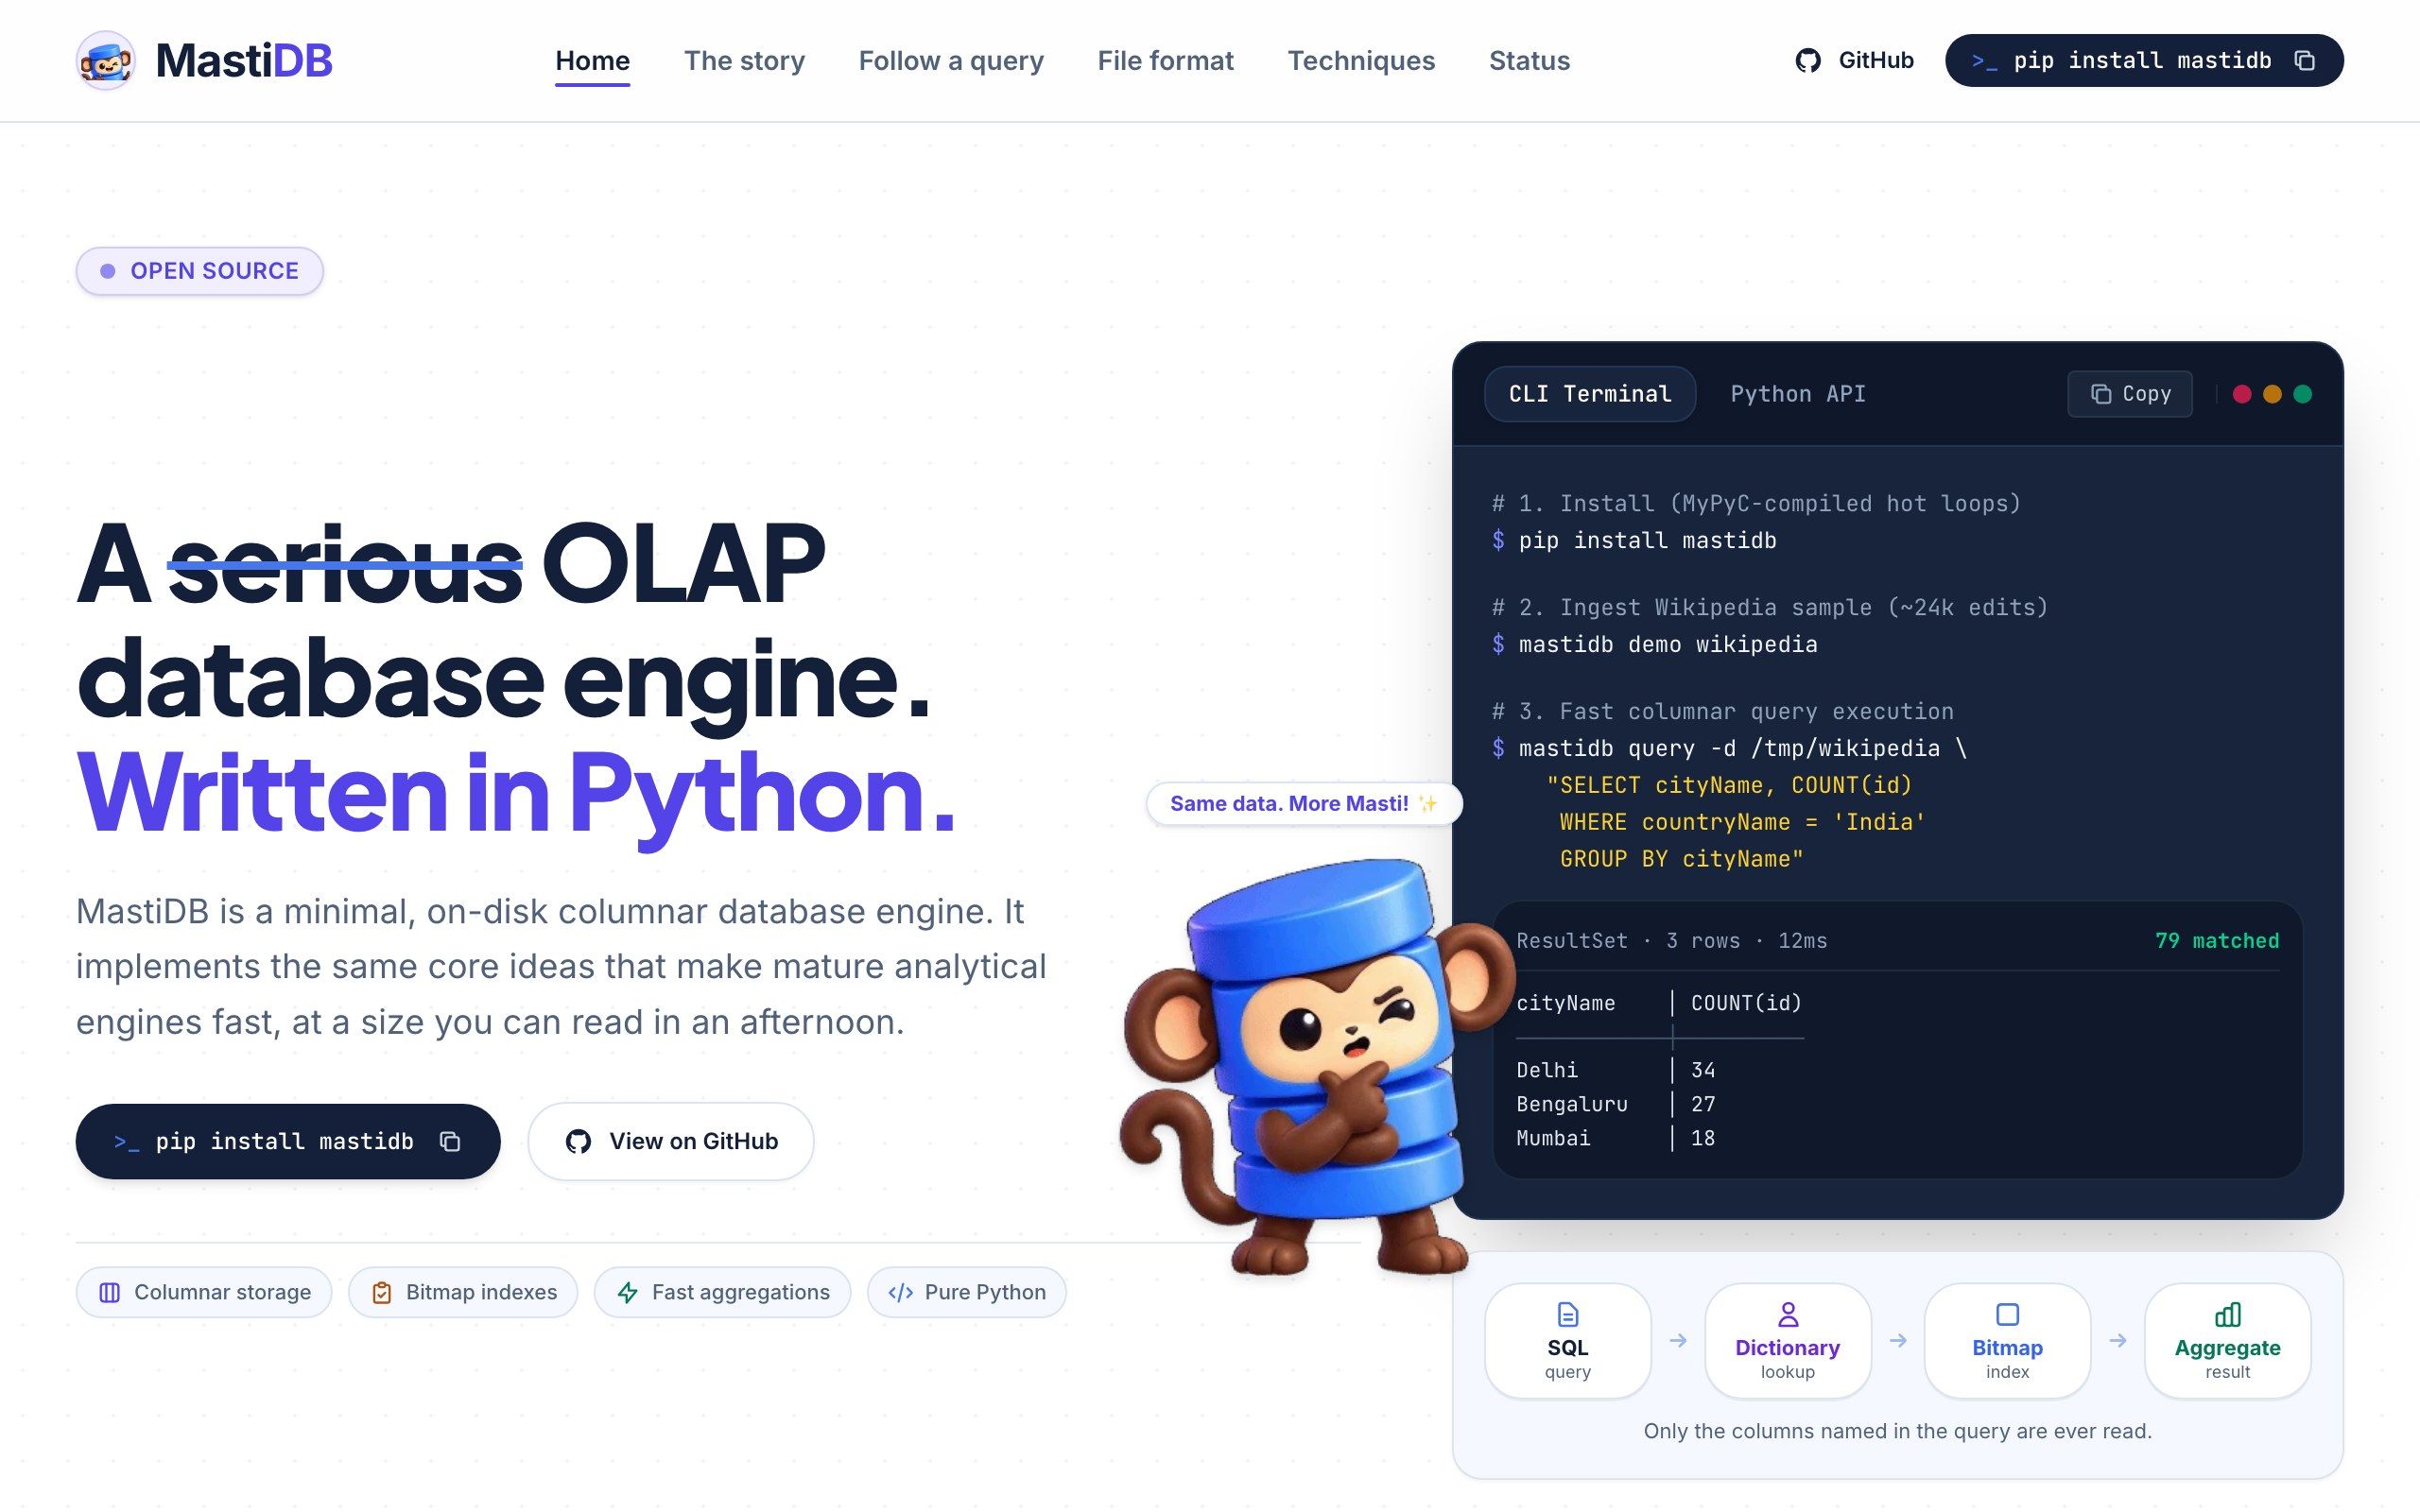
A single-node, disk-based columnar OLAP engine. It ingests CSV, TSV, JSON or ndJSON and answers a small SQL interface: SELECT, equality WHERE, GROUP BY, ORDER BY, LIMIT, and COUNT, SUM, AVG and COUNT(DISTINCT). The data stays on disk, filters use indexes, and a table works across many independent segments.
Why I built it
At Udaan I owned the Apache Druid layer behind Percept Insight. The daily question was simple: why is this funnel slow, and what can I change? Answering it meant reading Druid’s configs and sometimes its source. Around the same time I was watching Andy Pavlo’s database courses from CMU, which gave names to what I had seen in production.
I wanted to understand every major choice from the bytes on disk to the final result, so I built a small analytical database myself. The name comes from masti, Hindi for fun or mischief: a playful name for a fairly serious learning project.
How it works
- Storage. On-disk columnar segments with dictionary encoding.
- Filtering. Roaring Bitmap indexes answer equality filters without touching rows.
- Aggregation. Partial aggregates that merge across segments;
AVGstays a sum and a count until the merge. - Execution. Queries fan out across segments and merge, with the hot path compiled by MyPyC.
What I learned
The biggest improvements often did not come from making a loop faster. They came from looking at why the loop existed and whether the query needed it at all.
Building it showed me where the real decisions sit: a sorted dictionary makes sorting cheaper but its ids can’t cross segment boundaries, and columnar storage is great at aggregation but awkward when it must rebuild many rows.
Limits, stated plainly
It isn’t meant to replace Druid or ClickHouse, and it isn’t production-ready. Values are stored as strings, WHERE supports equality only, and there are no joins, updates or concurrency. Two known correctness bugs are listed in the roadmap.
Try it
pip install mastidb
mastidb ingest -d ./data -s ./source.csv
mastidb console -d ./data
Writing about it
- MastiDB: building an OLAP engine to understand one The full deep dive